Prime Intellect's New Mega MoE Kernel Boosts AI Training Speeds by Up to 55%
October 29, 2026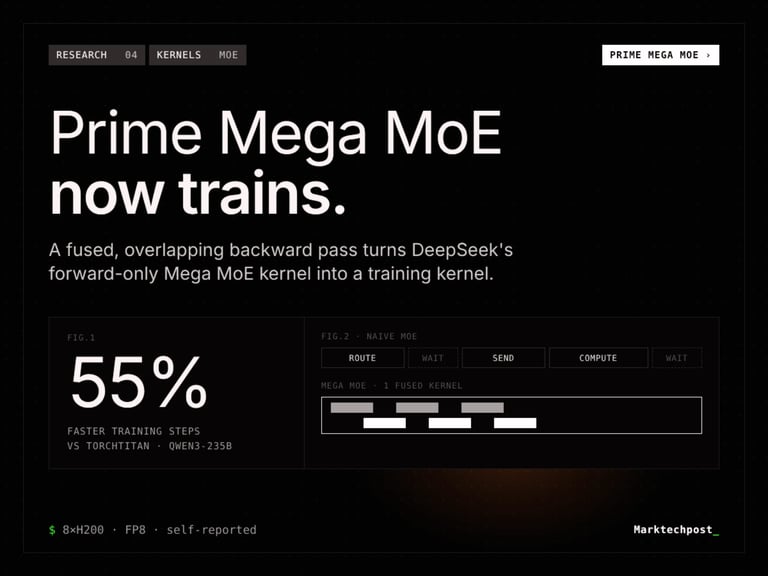

The update enables MoE training with reported training-step speedups of 32%–34% over the Prime-rl baseline and 48%–55% over TorchTitan, using 8×H200 nodes and FP8 data types.
Prime Mega MoE is a dispatch backend in the prime-rl trainer and requires prebuilt DeepGEMM wheels; users set model.moe.dispatch to mega_moe and choose precision (bf16, mxfp8, fp8, or fp8_bwd).
Prime Intellect released Prime Mega MoE, a training-extended fused Mega MoE kernel that adds a fast, overlapping backward pass to DeepSeek’s prior forward-only kernel.
Tests were conducted on NVIDIA Hopper and Blackwell GPUs, using 8×H200 nodes with 32 to 128 GPUs, 16,384-token sequences, FP8, and full activation checkpointing, testing Qwen3-30B-A3B and Qwen3-235B-A22B (128 experts, top-8 routing).
Forward speedups reach 3.11x for a Qwen3-30B-A3B MoE layer and backward speedups are 1.87x on the same model; for the larger Qwen3-235B-A22B MoE layer, forward gains are 2.17x and backward gains 1.24x.
Backward pass support was added to enable the fused kernel for training; supported data types include BF16, MXFP8 (Blackwell only), and blockwise FP8 (Hoppler only), with an fp8_bwd mode in prime-rl.
Compared options include Prime Mega MoE, DeepGEMM Mega MoE, TorchTitan + DeepEP, and AMD Primus MegaMoE, with Prime Mega MoE offering full backward support and fused compute-communication for MoE training.
Prime Mega MoE is a fused, overlapping MoE kernel that combines dispatch, two expert linear layers, SwiGLU, and combine into a single kernel, reducing idle GPU time by overlapping operations and minimizing intermediate tensors.
Summary based on 1 source
Get a daily email with more AI stories
Source
MarkTechPost • Oct 29, 2026
Prime Intellect Releases Prime Mega MoE: Trainable Fused MoE Kernel, 3.11x Faster Forward Pass