Topograph Revolutionizes Kubernetes and Slurm with Topology-Aware Scheduling for AI Workloads
September 23, 2026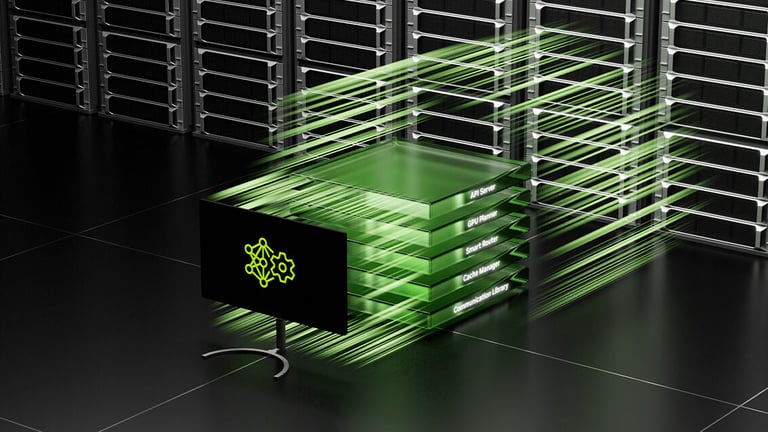

Topograph exposes Kubernetes topology by publishing node labels such as fabric.topograph.run/tier-0, tier-1, and accelerator.topograph.run/domain/sub-domain, enabling native affinity and topology-aware scheduling; KAI Scheduler or Kueue TAS can perform topology-aware gang scheduling.
It provides a common model with two core concepts—providers for discovery and normalization, and engines for translation to engine-specific formats—supporting Google Cloud, Lambda, Nebius, Nscale, OCI, Crusoe (Kubernetes-based), and on-premises InfiniBand or Spectrum-X fabrics.
Slurm users can generate topology configurations in tree or block formats, leverage per-partition YAML, and rely on Topograph to handle cluster-wide topology generation with optional automatic reconfiguration.
Getting started involves installing Topograph via package managers or Helm, configuring the provider and engine in topograph-config, and verifying health endpoints, topology labeling, and reconfiguration behavior when topology changes occur.
Slinky integration maps Kubernetes nodes to Slurm compute resources and writes topology data to ConfigMaps, with support for MNNVL systems and dynamic node reconciliation.
Topograph maintains a current topology view through five components—API Server, Node Observer, Node Data Broker, Provider, and Engine—and exposes API endpoints for querying and refreshing topology data.
It addresses fragmentation by discovering topology from cloud APIs or on-prem fabrics, normalizing to a canonical model, and publishing in formats consumable by Kubernetes (node labels), Slurm (topology.conf/tree), or Slinky (ConfigMaps).
As NVIDIA’s topology-aware workload tool, Topograph helps AI factories optimize GPU workload placement by maintaining an up-to-date view of topology across GPUs and interconnects like NVLink, InfiniBand, and Spectrum-X.
Deployment and operation steps cover Kubernetes (engine: k8s), Slurm (engine: slurm), and Slinky (engine: slinky) with Helm, verification of topology labels on nodes, and checks via health and metrics endpoints.
NFD integration publishes topology as NodeFeatureGroup objects and remains complementary to Kubernetes topology labels for native Pod affinity.
KAI Scheduler can apply hierarchical topology to group pods within defined topology boundaries, enabling required and preferred placements that optimize locality while honoring constraints.
Topograph operates within the DSX OS alongside Dynamic Resource Allocation and KAI Scheduler to enable topology-aware gang scheduling for AI workloads.
Summary based on 1 source
Get a daily email with more AI stories
Source
NVIDIA Technical Blog • Sep 22, 2026
Topology-Aware Workload Scheduling with NVIDIA Topograph