Ohio's Prometheus AI Supercluster Set to Revolutionize AI Training with 1 Million GPUs
October 19, 2026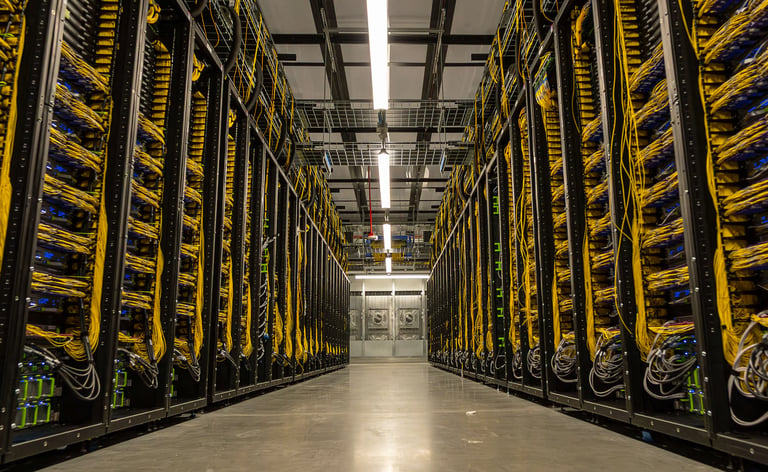

Prometheus features dedicated FPGA-like fabrics for building-level Ethernet and a Backend Aggregation network spanning 2 km to over 100 km, using Arista switches and Broadcom Jericho3 silicon to optimize GPU-to-GPU communication.
Networking design for AI workloads centers on a dedicated BE network and a hierarchical data-center fabric, connecting regions from short hops to long-haul links to minimize training slowdowns.
Prometheus uses three generations of racks—Catalina with GB200 NVL72, Clemente with GB300 NVL72, and Vera Rubin NVL72 on San Miguel—that progressively increase memory, compute, and power efficiency per rack.
Power and cooling are managed with Dynamo Dimmer power control, synchronized training power transients, and a mix of air-assisted liquid cooling and facility liquid cooling, with renewable energy use and IcePack-inspired Open Compute designs shared.
Dynamo Dimmer enables intelligent power capping, battery storage, and liquid cooling to sustain high-density training while mitigating electrical limits.
Energy sustainability includes coolant efficiency, utilities collaboration, and ongoing work with renewables to support large-scale training.
Future roadmap envisions expanding Prometheus with Vera Rubin GPUs, integrating next-gen hardware into the fabric, and applying Prometheus insights to Hyperion in Louisiana with similar cooling and grid-connected designs.
San Miguel platform will feature 72 Vera Rubin GPUs per rack, high HBM4 memory and very high FP4/FP8 compute, paired with full liquid cooling; Hyperion will be Meta’s next 5 GW-scale supercluster in Louisiana with closed-loop cooling and direct grid connectivity.
Prometheus delivers high efficiency, with over 85% goodput in pre-training and more than 90% in reinforcement learning runs for Muse Wonder.
Vytautas Valinskas authored the piece, drawing on Meta’s public engineering blog and related sources for Muse Spark Open and Muse Wonder pricing.
Prometheus serves as a template for future efforts, with Hyperion planned as a larger follow-on and continued model releases aligned with hardware expansion.
Operational maturity includes firmware automation, fleet health telemetry, signal screening, power-delivery stress testing, precision liquid cooling, and proactive maintenance across GB200/GB300 deployments.
Summary based on 3 sources
Get a daily email with more Tech stories
Sources
Engineering at Meta • Oct 19, 2026
Inside Prometheus: Meta’s Journey to a Gigawatt-Scale Supercluster
Unite.AI • Oct 19, 2026
Meta Details Prometheus Supercluster Scaling Toward 1 Million GPUs